blog-blogachyuthan.vercel.app/blog/when-memory-layout-assumptions-collide-vllm-kv-cache

Newest post · vLLM

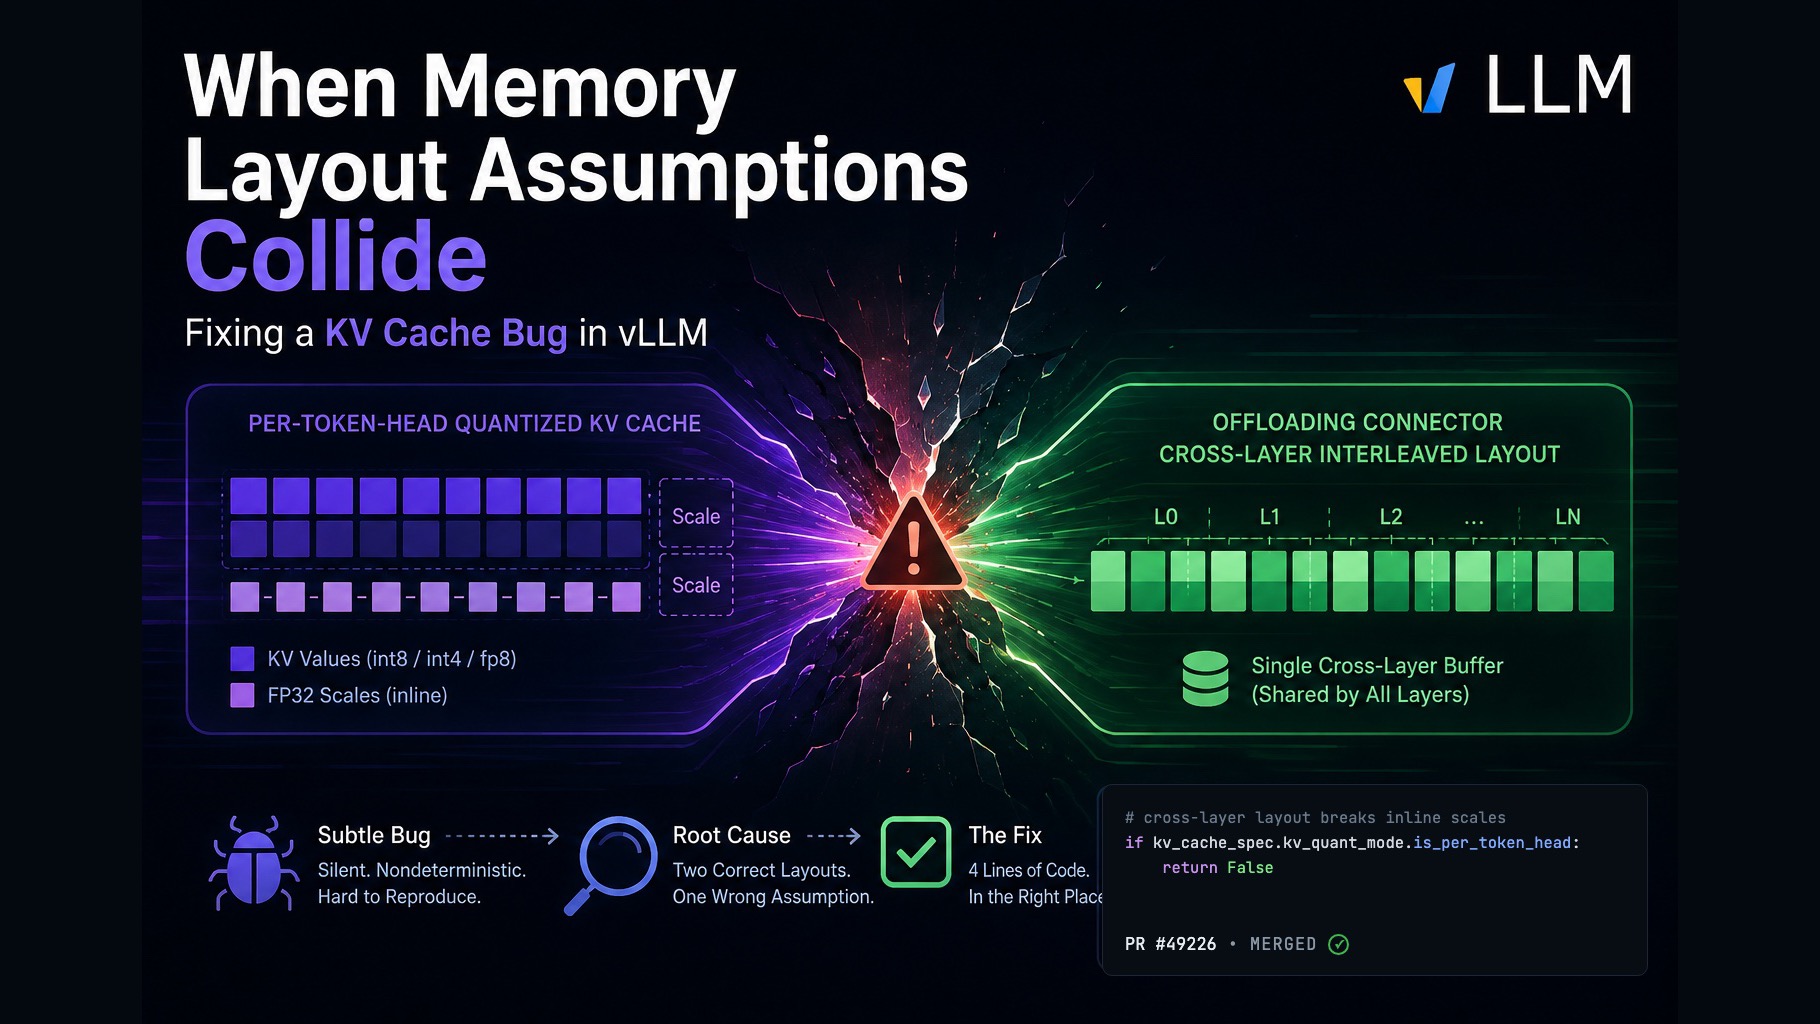
When Memory Layout Assumptions Collide: Fixing a KV Cache Bug in vLLM

Two independently correct components — KV offloading and per-token-head quantization — corrupted generations the moment they were combined. The fix was four lines. Finding where those four lines belonged took a trip through GPU memory layouts.
vLLMKV cachequantizationGPU memory

Writing

Blog

Deep dives from debugging production ML systems and shipping open-source fixes.

All posts

Every post, newest first.

5

OSS

Browse by open-source project.

Research

Papers and research write-ups.